Survey
* Your assessment is very important for improving the work of artificial intelligence, which forms the content of this project
Average Run Time (S)
DFC-Manhattan
DFC-Max
DFC-Euclidean
PHDCluster
1800
1600
1400
1200
1000
800
600
400
200
0
128x128
256x256
512x512
1024x1024 2048x2048
Data Size (number of tuples)
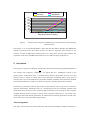
Figure 6.
Running Time Comparison of PHDCluster with other Density Clustering using
Different metrics
From Figure 6, we see that DC-Manhattan is faster than DC-Max and Dc-Euclidan. But PHDCluster
method is much faster than all of them on these five data sets. Especially when the data set size
increases, the time of PHDCluster method increases at a much lower rate than other methods. The
experiment results show that PHDCluster method is more scalable for large spatial data set.
5. Conclusion
In this paper, we propose an efficient P-tree Hawaiian density based clustering algorithm (PHDCluster),
with average time complexity, O ( dn n ) ), for spatial data sets.
PHDCluster exploits a new
distance metric, the Hawaiian metric, to calculate density functions using Peano Trees (P-trees). The
Hawaiian metric is natural for spatial data and the calculation of Hawaiian metrics using P-tree is
extremely fast. Our proposed method has comparable cardinality scalability with other density methods
for small and medium size of data, but is shown to be superior regarding dimensional scalability.
Our method is particularly useful for data streams. In data streams, such as large sets of transactions,
remotely sensed images, multimedia video, etc., new data keeps on arrival continually. Therefore both
speed and accuracy are critical issues. Achieving high speed using P-tree, and high accuracy using the
weighted Hawaiian metrics provides a density based clustering method that is well suited to the
clustering of steam data. Besides spatial data, our method also has potential applications in other areas,
such as DNA micro array and medical image analysis.
Acknowledgement
This paper would not have been done without the help of all the DataSurgies at NDSU and friends. A