Survey
* Your assessment is very important for improving the work of artificial intelligence, which forms the content of this project
* Your assessment is very important for improving the work of artificial intelligence, which forms the content of this project
2 / Average-Case Analysis of Algorithms and Data Structures
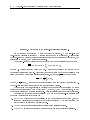
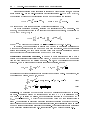
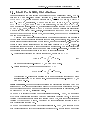
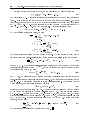
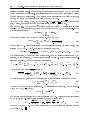
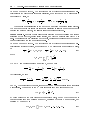
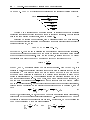
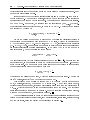
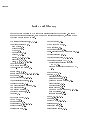
Figure 1.
Methods used in the average-case analysis of algorithms.
Let us consider an algorithm A with complexity measure . The worst-case and
best-case complexities of algorithm A over In are dened in an obvious way. Determining
the worst-case complexity requires constructing extremal congurations that force n , the
restriction of to In , to be as large as possible.
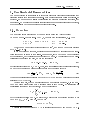
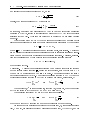
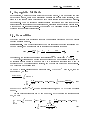
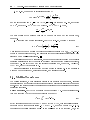
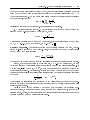
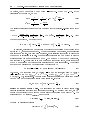
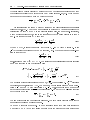
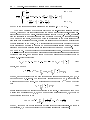
The average-case complexity is dened in terms of the probabilistic input model:
X
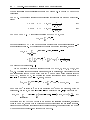
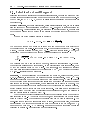
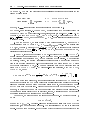
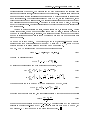
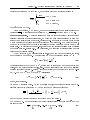
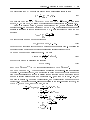
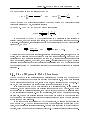
n [A] = Efn [A]g = k Prfn [A] = kg;
k
where Ef:g denotes expected value and Prf:g denotes probability with respect to the
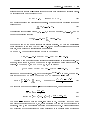
probability distribution over In . Frequently, In is a nite set and the probabilistic model
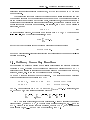
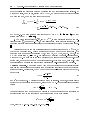
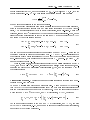
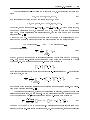
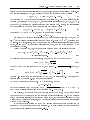
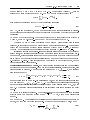
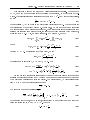
assumes a uniform probability distribution over In . In that case, n [A] takes the form
X
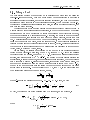
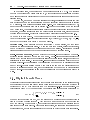
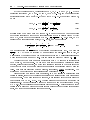
n [A] = I1 kJnk ;
n k
where In = jIn j and Jnk is the number of inputs of size n with complexity k for algorithm A.
Average-case analysis then reduces to combinatorial enumeration.
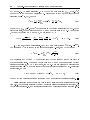
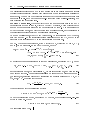
The next step in the analysis is to express the complexity of the algorithm in terms
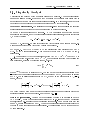
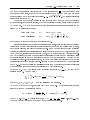
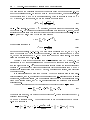
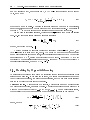
of standard functions like n (log n) (log log n) , where , , and are constants, so that
the analytic results can be easily interpreted. This involves getting asymptotic estimates.
The following steps give the route followed by many of the average-case analyses that
appear in the literature (see Figure 1):
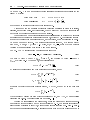
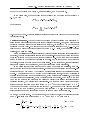
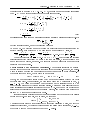
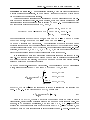
1. RECUR: To determine the probabilities or the expectations in exact form, start by
setting up recurrences that relate the behavior of algorithm A on inputs of size n to
its behavior on smaller (and similar) inputs.
2. SOLVE: Solve previous recurrences explicitly using classical algebra.
3. ASYMPT: Use standard real asymptotics to estimate those explicit expressions.