Survey
* Your assessment is very important for improving the work of artificial intelligence, which forms the content of this project
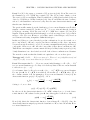
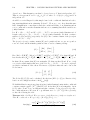
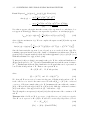
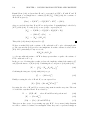
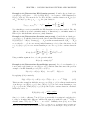
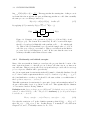
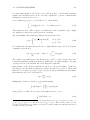
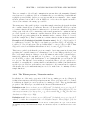
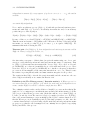
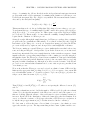
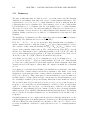
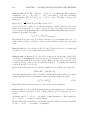
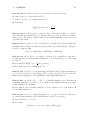
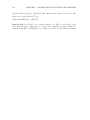
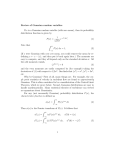
126 CHAPTER 3. GAUSSIAN RANDOM VECTORS AND PROCESSES depend on y. This fluctuation can then be denoted as a rv V that is independent of Y . 2 ) and V is Thus we can represent X as X = â¢( X / Y )Y + V where V â N (0, (1 â¢2 ) X independent of Y . As will be seen in Chapter 10, this simple form for the conditional distribution leads to important simplifications in estimating X from Y . We now go on to show that this same kind of simplification occurs when we study the conditional density of one Gaussian random vector conditional on another Gaussian random vector, assuming that all the variables are jointly Gaussian. Let X = (X1 , . . . , Xn )T and Y = (Y1 , . . . , Ym )T be zero-mean jointly Gaussian rvâs of length n and m (i.e., X1 , . . . , Xn , Y1 , . . . , Ym are jointly Gaussian). Let their covariance matrices be [KX ] and [KY ] respectively. Let [K] be the covariance matrix of the (n+m)-rv (X1 , . . . , Xn , Y1 , . . . , Ym )T . The (n+m) ⥠(n+m) covariance matrix [K] can be partitioned into n rows on top and m rows on bottom, and then further partitioned into n and m columns, yielding: 2 3 [KX ] [KX ·Y ] 5. [K] = 4 (3.38) T [KX ·Y ] [KY ] Here [KX ] = E [X X T ], [KXh·Y ] = E [X Y T ], and i[KY ] = E [Y YhT ]. Note that if X and i Y T T have means, then [KX ] = E (X X )(X X ) , [KX ·Y ] = E (X X )(Y Y ) , etc. In what follows, assume that [K] is non-singular. We then say that X and Y are jointly non-singular, which implies that none of the rvâs X1 , . . . , Xn , Y1 , . . . , Ym can be expressed as a linear combination of the others. The inverse of [K] then exists and can be denoted in block form as 2 3 [B] [C] 5. [K 1 ] = 4 (3.39) [C T ] [D] The blocks [B], [C], [D] can be calculated directly from [KK but for now we simply use them to find fX |Y (x |y ). 1] = [I] (see Exercise 3.16), We shall find that for any given y , fX |Y (x |y ) is a jointly-Gaussian density with a conditional covariance matrix equal to [B 1 ] (Exercise 3.11 shows that [B] is non-singular). As in (3.37), where X and Y are one-dimensional, this covariance does not depend on y . Also, the conditional mean of X , given Y = y , will turn out to be [B 1 C] y . More precisely, we have the following theorem: Theorem 3.5.1. Let X and Y be zero-mean, jointly Gaussian, jointly non-singular rvâs. Then X, conditional on Y = y, is N [B 1 C] y , [B 1 ] , i.e., fX|Y (x|y) = exp n 1 2 ⣠x + [B 1 C] yT (2â¡)n/2 â ⣠[B] x + [B p det[B 1] âo 1 C] y . (3.40)